Same question, different answer: where inconsistent AI answers come from
My first real use of ChatGPT was Christmas 2022, for what to cook, what to do with the leftovers and a few dad jokes for the table, and my second was our field teams’ quarterly reports.
A bad leftovers recipe costs you a dinner, while a wrong growth figure costs a micro-entrepreneur the coaching they needed. Same tool, very different stakes, and the reports were where I learned where inconsistent AI answers really come from.
In the first post in this series I wrote about the two weeks every quarter my wife Sahar and I spent reading what our Peace Through Prosperity field teams sent back. By then Egypt had joined, three teams were reporting and the pile was only getting bigger, and at the end of 2022 there was finally a tool that could read faster than we could. So we handed it the reading.
What happened when we pointed it at the field?
It was much faster, and it was also wrong, which we found out the same day.
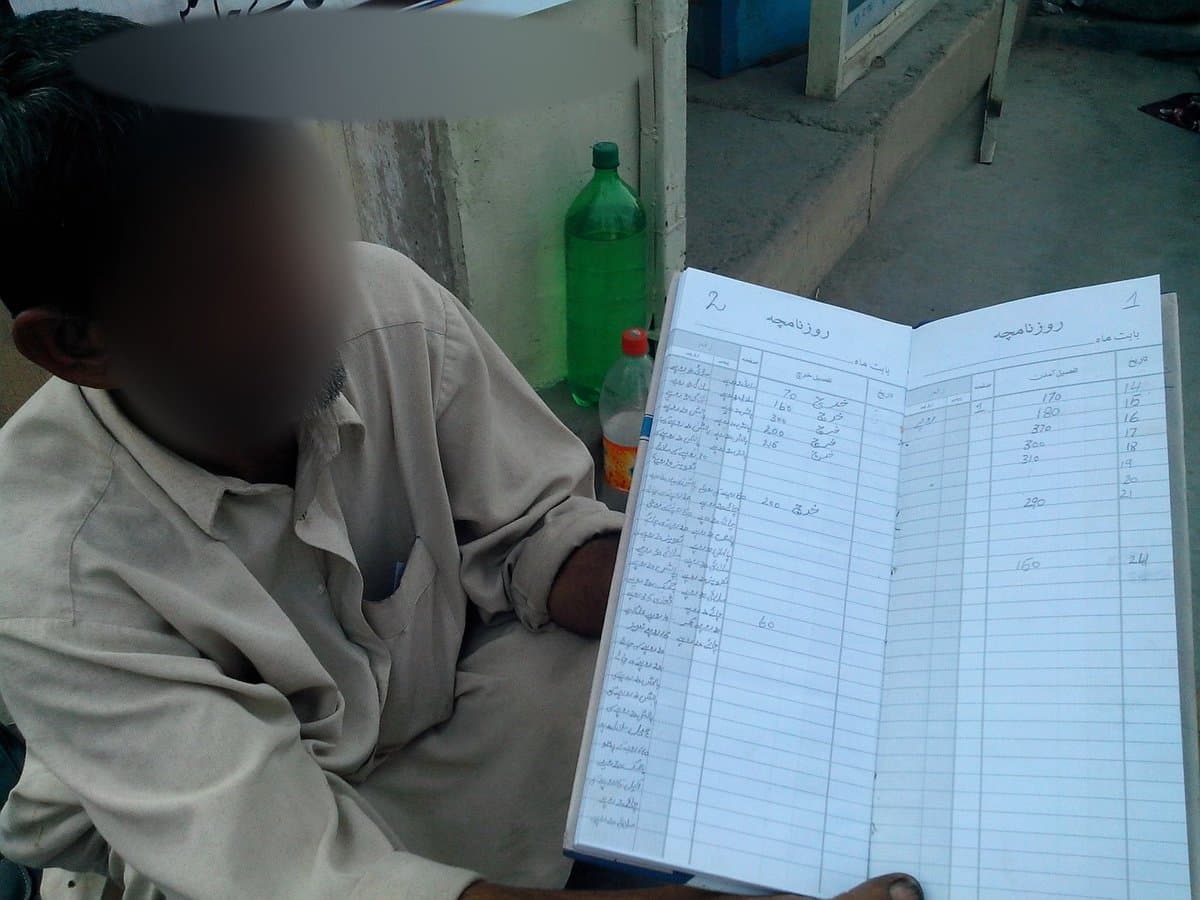
Sahar had done the same analysis by hand in Google Sheets, and when the AI’s version came back we compared notes and they didn’t agree. We argued a little about who was right, the AI or Sahar and her Google Sheet, so we walked through one participant’s numbers together, line by line.
Sahar was right, and we laughed about the AI not being quite so smart after all.
The sheet won because we trusted it, rather than because a spreadsheet is clever: the baseline was solid, and we knew every figure in it and every person behind every figure. From then on, the AI was the one that had to explain itself.
One of those early conversations survives in my archive. In July 2023 I gave it four months of data for one cohort of twelve entrepreneurs and asked a simple question, who were the top five by growth, and then a second one, who were the top three and the bottom three by percentage growth?
One entrepreneur was in the top five and the bottom three: the same data, in the same session, with the same word read two ways.
Where do inconsistent AI answers come from?
Because “growth” can mean two different things, and the first time I asked, it picked one without saying so.
The first time, it ranked the entrepreneurs by the change in revenue; the second time I asked for percentage growth, and it gave me that. Both are reasonable measures, but a micro-business growing from a very small base looks heroic in percentages and invisible in absolute terms, and a larger one looks the other way round. It noted each measure in a single line under its table, and it never pointed out that its two rankings measured different things or asked which one I needed.
So the maths was fine; what it never did was ask what I meant.
And it couldn’t have known, because what we meant was never written down. Sahar knew what we meant by growth, and so did I, and which version mattered depended on the decision we were making that quarter, whether that was who needed more coaching or who was ready for the next step. That knowledge lived in our heads rather than in the data.
I’ve started calling this definition debt: every word your organisation uses without ever writing down what it means. People pay it off quietly every time they translate, but a machine can’t, so it guesses, and it guesses with confidence.
What did the rulebook teach us?
A couple of days later I wrote a rule to catch that kind of answer before it reached us, then another, then a paragraph, and the rulebook went from a few lines to many paragraphs very quickly.
It kept growing because the world it described kept moving. Not every variable coming in from the field could be defined in advance, some of the ones we had defined changed over time, and every new rule was a definition we hadn’t written down before.
So the rulebook was a symptom rather than a fix: we were paying off our definition debt one paragraph at a time, and the debt was growing faster than the payments.
I see the same thing in organisations now, with a different name on it: the prompt library that gets longer every week, the “always check this” note pinned in the team channel, the one person everyone asks before trusting the dashboard. When the rules keep growing, they are telling you how much was never defined.
What came after the rules?
In 2024 we tried to build our own way out, using Replit, a coding platform, to answer the question for ourselves and automate the process end to end.
Then we changed direction, and instead of writing a rule for every variable we started giving the machine what Sahar and I carried in our heads.
First came a context layer, so it knew what we knew: what the programme was for, and what our words meant.
Into it went everything the field had ever sent us: a complete export of every team’s WhatsApp channels, shared with the teams’ agreement, our emails with partners and team members, voice notes transcribed, images each explained in words, and the reports we and the teams had written, in several languages.
All of it sat in one large document, stored on our own machines, which the AI read in as context. Team names were in it, but participants’ names were not: those stayed in the individual sheets.
Then a knowledge map built on top of it, with the quantitative data and the qualitative stories kept apart, so a figure from a ledger and a sentence from an interview could never be blended into one confident answer.
Each step was less about the AI and more about writing down what we already knew, and the hard part was always the definitions rather than the technology.
What happens when 300 people ask?
Picture the same thing with more people asking. A midsized company switches on an AI assistant across its documents, chat and email, and two managers ask it the same question in the same week: how many customers did we lose last quarter? One answer counts accounts and the other counts contracts, both arrive with the same confidence, and neither manager knows the other asked.
That’s definition debt at scale. At Peace Through Prosperity two people held the definitions, but in a 300-person organisation they’re spread across hundreds of heads, and some of those heads disagree.
The fix I trust most is the plainest one. In a London borough where I led digital, data and AI work, we used AI to write up discovery sessions, and one rule held it together: nothing moved forward until someone who had been in the room read the write-up back and confirmed it.
That’s Sahar’s sheet turned into a rule: the person who knows checks the translation before anyone acts on it.
And if you want somewhere to start, start smaller than a tool. Write down the five words your leadership team argues about most, and what each one means, because inconsistent AI answers start in the room: if you can’t agree on the definitions there, no AI will agree on them for you.
So here’s my question
If two of your managers asked your AI the same question tomorrow, would they get the same answer? And would either of them know if they didn’t?
If you’ve seen this in your organisation, I’d love to compare notes over a virtual chai: grab 20 minutes on my calendar.
This is the second of three posts on what happens when the field reports faster than anyone can read it. Previous: Your managers aren’t the problem. They’re the integration layer. Next: build vs buy AI, and the product I never built.
Thank you for reading. If you’re new here, I’m Kubair Shirazee, I help people, teams, organisations and communities navigate past the status quo and explore better ways of collaborating, deciding and delivering impact, increasingly with AI.